From Dawn Shift to Data: Why Control Matters Now
It’s 5:10 a.m., the cross-dock lights blink on, and the floor hums to life. The second the doors open, an amr controller starts assigning routes, charge windows, and safe passes so the crew can breathe. In one pilot across Bogotá and Monterrey, congestion dropped 24% and pick variance fell by 17%—simple changes in task timing and priorities did the heavy lifting (sí, nothing flashy). Yet teams still ask: if the numbers look good, why do handoffs feel rough, and why do bots stall at the worst moments? SLAM maps are stable, edge computing nodes are in place, and the dashboards shine. But day-to-day, people chase resets, radio hiccups, and small drifts that grow. The big question is not “do we have robots,” but “do we have control that adapts at human speed?” — funny how that works, right? We need to zoom in on the decisions inside the loop, where seconds matter and trust is built. Let’s unpack the gap, then compare what actually shifts outcomes next.
The Hidden Friction in Today’s Robot Control
Why do users still feel the friction?
In a modern robot control system, the pain rarely sits in the headline features. It sits between them. Look, it’s simpler than you think: users want smooth orchestration, not heroics. But three quiet issues show up again and again. First, network jitter ruins pacing. When Wi‑Fi gets busy, ROS 2 middleware can recover, yet poor QoS choices push command-to-actuation delay past safe bounds. It feels random to operators—until a near miss. Second, integrations age overnight. A CAN bus bridge here, a warehouse API there, and soon every forklift route depends on one fragile adapter. One firmware update, and the glue code breaks—oye, nadie quiere eso. Third, power is noisy. Cheap power converters produce spikes that cause sensor blips; then sensor fusion throws false obstacles. The bot stops, the line stalls, and the “why” looks invisible because logs seem clean.
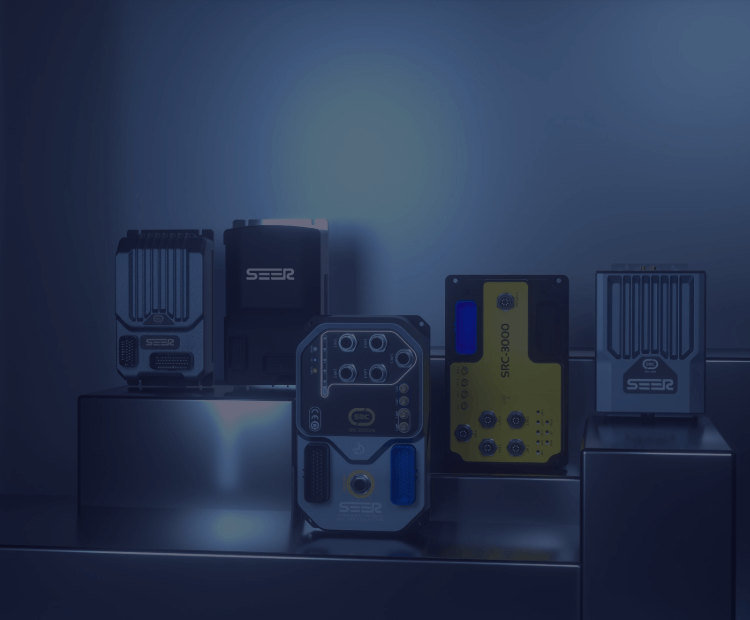
There are also human costs. People hate babysitting maps. When SLAM drifts after a layout tweak, the fix comes late, and a small remap becomes a long night. Tech leads dread mixed fleets too; two vendors, two toolchains, and kinematics tuned by different teams. Data exists, but not in the same place or at the same time. And support? Tickets bounce between network, safety, and hardware suppliers. Meanwhile, operators still tap pause because “the bot gets jumpy near the dock”—a classic symptom of bad QoS under load. The pattern is clear: the failures are not dramatic; they are boring. That’s why they hide so well—funny, and not funny. The best amr controller reduces this invisible friction by default, not with more features, but with tighter timing, cleaner updates, and predictable behavior across real messes.
Comparing What’s Next: Principles Shaping the Next Wave
What’s Next
Forward-looking control isn’t about one feature; it’s about how the pieces react together under stress. Two principles matter now. First, end-to-end determinism. Commands should hit p95 latency targets even when traffic spikes, with backoffs and priorities tuned at the edge. That means better QoS presets, smarter retries, and local autonomy that holds for seconds if the link wobbles. Second, integration without glue. Instead of one-off bridges, a modular robot control system exposes standard drivers, safe API contracts, and versioned behavior—so updates don’t break routes. Add a clean power path, and those power converters stop polluting your sensors. Mix in health checks for kinematics and safety I/O, and faults become visible before shifts begin. Not glamorous, but real. And real is what moves pallets.
So how do you choose—today, not mañana? Go semi-formal, compare like-for-like, and measure across your worst hour. Advisory close, con cariño: three metrics decide it. One, command-to-actuation latency under load: target p95 under 70 ms with congestion (or you’ll feel the wobble at corners). Two, recovery time from map or link disruptions: SLAM relocalization plus route rebuild in under 30 seconds, with no human tap-through—because hands are busy. Three, integration depth you can trust: driver coverage for CAN bus and PLCs, plus ROS 2 interoperability, validated by a full mixed-fleet test in your layout (not a lab maze). If a platform meets these, the rest is fit and polish—oye, that’s the truth. For teams comparing options and planning the next cycle, you’ll find thoughtful engineering and practical patterns at SEER Robotics.